Worked example: spectral mixture on Mauna Loa CO2
Source:vignettes/articles/spectral-mixture-co2.Rmd
spectral-mixture-co2.RmdA spectral-mixture kernel learns a stationary covariance from the
data’s spectrum instead of from a kernel structure chosen in advance.
This example compares it with a composite kernel built from knowledge of
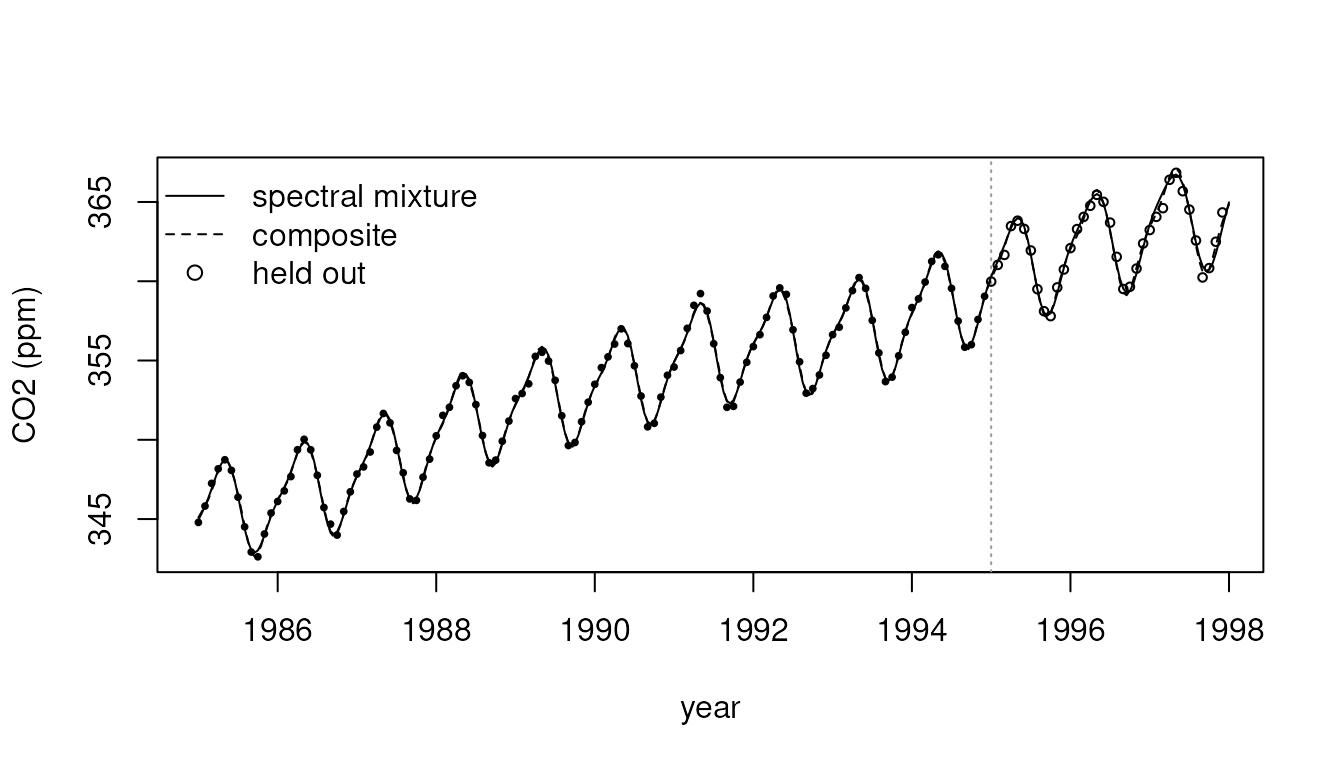
the CO2 record, on the held-out years of datasets::co2.
The code below is the script
inst/examples/spectral-mixture-co2.R, installed as
system.file("examples", "spectral-mixture-co2.R", package = "gaussianprocesses");
it is run as-is to produce this page.
# Spectral mixture versus a structured composite kernel on Mauna Loa CO2
#
# Monthly atmospheric CO2 concentrations (datasets::co2) from 1985 to 1994
# train two models, and 1995 to 1997 are held out. Both estimate a linear
# trend by generalized least squares (linear_mean()) and their kernel
# hyperparameters and noise by maximum likelihood:
#
# - a composite kernel built from prior knowledge: a smooth trend
#   deviation, an annual cycle that drifts slowly, and short-term
#   variation;
# - a spectral mixture with three components, initialized from the
#   spectrum of the detrended training series.
#
# Each model is scored by the log predictive density of the 36 held-out
# months, the sum of the log densities of the observations under the
# predictive distribution including noise, and by the RMSE of the
# predictive mean.

library(gaussianprocesses)

years <- as.numeric(stats::time(datasets::co2))
level <- as.numeric(datasets::co2)
training <- years >= 1985 & years < 1995
held_out <- years >= 1995

composite <- sum_kernel(
  rbf_kernel(variance = 1, length_scale = 10),
  product_kernel(
    periodic_kernel(variance = 4, length_scale = 1, period = 1),
    rbf_kernel(variance = 1, length_scale = 50)
  ),
  rbf_kernel(variance = 0.5, length_scale = 1)
)
composite_model <- optimize_gp(
  years[training],
  level[training],
  kernel = composite,
  noise_variance = 0.05,
  mean = linear_mean(),
  n_starts = 3
)

detrended <- stats::residuals(stats::lm(level[training] ~ years[training]))
initial <- initialize_spectral_mixture(
  years[training],
  detrended,
  n_components = 3
)
initial
#> SumKernel(
#>   SpectralComponent(weight=4.06361, frequency=1.00162, spectral_variance=0.00137972)
#>   SpectralComponent(weight=0.305441, frequency=1.9938, spectral_variance=0.00107715)
#>   SpectralComponent(weight=0.250565, frequency=0.13086, spectral_variance=0.00066307)
#> )

spectral_model <- optimize_gp(
  years[training],
  level[training],
  kernel = initial,
  noise_variance = 0.05,
  mean = linear_mean(),
  n_starts = 3
)
spectral_model$kernel
#> SumKernel(
#>   SpectralComponent(weight=4.45137, frequency=1.00171, spectral_variance=3.57916e-06)
#>   SpectralComponent(weight=0.225407, frequency=1.98219, spectral_variance=0.00093191)
#>   SpectralComponent(weight=0.367325, frequency=0, spectral_variance=0.0192326)
#> )

score <- function(model) {
  prediction <- predict_gp(model, years[held_out])

  c(
    log_marginal_likelihood = log_marginal_likelihood(model),
    held_out_log_predictive_density = sum(
      stats::dnorm(
        level[held_out],
        mean = prediction$mean,
        sd = prediction$observation_sd,
        log = TRUE
      )
    ),
    held_out_rmse = sqrt(mean((prediction$mean - level[held_out])^2))
  )
}

scores <- rbind(
  composite = score(composite_model),
  spectral_mixture = score(spectral_model)
)
scores
#>                  log_marginal_likelihood held_out_log_predictive_density
#> composite                      -34.67554                       -19.14834
#> spectral_mixture               -38.94706                       -19.79090
#>                  held_out_rmse
#> composite            0.3202286
#> spectral_mixture     0.3922130

grid <- seq(1985, 1998, by = 1 / 24)
composite_path <- predict_gp(composite_model, grid)
spectral_path <- predict_gp(spectral_model, grid)

plot(
  years[training | held_out],
  level[training | held_out],
  pch = ifelse(held_out[training | held_out], 1, 20),
  cex = 0.6,
  xlab = "year",
  ylab = "CO2 (ppm)"
)
abline(v = 1995, col = "grey60", lty = 3)
lines(grid, composite_path$mean, lty = 2)
lines(grid, spectral_path$mean)
legend(
  "topleft",
  legend = c("spectral mixture", "composite", "held out"),
  lty = c(1, 2, NA),
  pch = c(NA, NA, 1),
  bty = "n"
)
Results
On the held-out months, the composite kernel has the higher log predictive density: -19.1 for the composite kernel and -19.8 for the spectral mixture, with RMSE 0.32 and 0.39 ppm. Both results are reported whichever is better: this is one split of one series, not a benchmark.
The spectrum of the detrended series puts the initial components at the annual cycle, its first harmonic, and a slow oscillation. After optimization one component has moved to frequency 0, where a spectral component is an RBF kernel: the mixture has found the smooth deviation from the linear trend on its own, which the composite kernel was given as a separate RBF term.
The spectral-mixture likelihood is strongly multimodal, and here the
initialization does most of the work. In four seeded trials, not run on
this page, with the three frequencies drawn uniformly between 0 and 6
cycles per year instead, a single optimizer start always stopped at a
worse optimum: held-out log predictive densities between -82 and -39,
and log marginal likelihoods between -268 and -135. The three starts
around the initialization, which optimize_gp() displaces by
one frequency-resolution bin each, are a guard against a slightly
misplaced initialization; on this split they reach the same optimum as
one start.