Multidimensional Gaussian Processes and ARD
Source:vignettes/v05-multidimensional-ard.Rmd
v05-multidimensional-ard.RmdScaled distance
For D-dimensional inputs, stationary kernels use the scaled distance
r^2(x,x') = \sum_{d=1}^D \frac{(x_d-x_d')^2}{\ell_d^2}.
If
\ell_1=\cdots=\ell_D=\ell,
the kernel is isotropic.
If the \ell_d differ, the model uses automatic relevance determination (ARD).
Example
x <- rbind(
  c(0, 0),
  c(1, 0),
  c(0, 1)
)

isotropic <- rbf_kernel(
  variance = 1,
  length_scale = 1
)

ard <- rbf_kernel(
  variance = 1,
  length_scale = c(0.4, 2)
)

evaluate_kernel(isotropic, x)
#>           [,1]      [,2]      [,3]
#> [1,] 1.0000000 0.6065307 0.6065307
#> [2,] 0.6065307 1.0000000 0.3678794
#> [3,] 0.6065307 0.3678794 1.0000000
evaluate_kernel(ard, x)
#>            [,1]       [,2]       [,3]
#> [1,] 1.00000000 0.04393693 0.88249690
#> [2,] 0.04393693 1.00000000 0.03877421
#> [3,] 0.88249690 0.03877421 1.00000000
With \ell_1=0.4 and \ell_2=2, covariance changes more rapidly along the first input dimension.
That is a statement about the covariance geometry of this model.
It is not a causal importance claim.
Parameter paths
Vector length scales become separate optimizer paths:
kernel_parameters(
  ard,
  flatten = TRUE
)
#>        variance length_scale[1] length_scale[2]
#>             1.0             0.4             2.0
A single dimension can therefore be updated independently:
ard_updated <- update_kernel_parameters(
  ard,
  c("length_scale[2]" = 3)
)

kernel_parameters(
  ard_updated,
  flatten = TRUE
)
#>        variance length_scale[1] length_scale[2]
#>             1.0             0.4             3.0
Reproducible two-dimensional simulation
simulation <- gp_simulation_scenario(
  "ard_2d",
  n = 40,
  seed = 1729
)

head(simulation$x)
#>             x1        x2
#> [1,] -2.000000 1.0000000
#> [2,] -1.897436 0.9870503
#> [3,] -1.794872 0.9485364
#> [4,] -1.692308 0.8854560
#> [5,] -1.589744 0.7994428
#> [6,] -1.487179 0.6927244
simulation$kernel
#> Matern-3/2(variance=1.4, length_scale=c(0.45, 2.2))
Fit the model with the same known covariance family:
model <- fit_gp(
  simulation$x,
  simulation$observed,
  kernel = simulation$kernel,
  noise_variance = simulation$noise_variance
)

prediction <- predict_gp(
  model,
  simulation$x,
  observation_noise_variance = 0
)

sqrt(
  mean(
    (prediction$mean - simulation$latent)^2
  )
)
#> [1] 0.1196077
ARD and optimization
ARD parameters can also be estimated through the same flattened parameter interface:
estimated <- optimize_gp(
  simulation$x,
  simulation$observed,
  kernel = rbf_kernel(
    variance = 1,
    length_scale = c(1, 1)
  ),
  noise_variance = 0.04,
  optimize_noise = FALSE
)

kernel_parameters(
  estimated$kernel,
  flatten = TRUE
)
This example is not evaluated in the vignette; the same code is
directly reproducible in an interactive R session. The additive-model
section below estimates hyperparameters with optimize_gp()
and shows its results.
Interpretation
A useful interpretation is geometric:
\frac{|x_d-x_d'|}{\ell_d}
is the dimension-specific standardized separation used by the covariance function.
Large \ell_d makes the process vary slowly along dimension d. Small \ell_d allows faster changes.
This interpretation remains model-dependent. It should not be promoted to causal or mechanistic importance without additional assumptions.
Additive models
Every kernel above acts on all input columns.
select_dimensions() restricts a kernel to some of them. For
a set of columns S,
k_S(x, x') = k(x_S, x'_S).
This is k composed with a linear projection, so it is positive semidefinite whenever k is. A sum of restricted kernels,
k(x, x') = \sum_j k_j(x_{S_j}, x'_{S_j}),
is the covariance of an additive function f(x) = \sum_j f_j(x_{S_j}) with independent components f_j. An additive model cannot represent interactions between columns in different components. In exchange, each component is a function of fewer inputs, which takes fewer observations to learn.
The kernel below has a one-dimensional component in x_1 and a two-dimensional ARD component in (x_2, x_3):
additive <- sum_kernel(
  select_dimensions(rbf_kernel(), 1),
  select_dimensions(rbf_kernel(length_scale = c(1, 1)), 2:3)
)

additive
#> SumKernel(
#>   SelectDimensions(columns=1,
#>     RBF(variance=1, length_scale=1)
#>   )
#>   SelectDimensions(columns=c(2, 3),
#>     RBF(variance=1, length_scale=c(1, 1))
#>   )
#> )
The selection is not a hyperparameter and adds no level to parameter paths. ARD length scales have one value per selected column:
names(kernel_parameters(additive, flatten = TRUE))
#> [1] "kernel1.variance"        "kernel1.length_scale"
#> [3] "kernel2.variance"        "kernel2.length_scale[1]"
#> [5] "kernel2.length_scale[2]"
Simulate data from an additive function of three inputs, f(x) = \sin(2 x_1) + 1.5 \exp(-(x_2^2 + x_3^2)/2), with noise standard deviation 0.1:
set.seed(2025)

f1 <- function(x1) sin(2 * x1)
f2 <- function(x2, x3) 1.5 * exp(-(x2^2 + x3^2) / 2)
latent <- function(x) f1(x[, 1]) + f2(x[, 2], x[, 3])

x_train <- matrix(runif(3 * 100, -2, 2), ncol = 3)
y_train <- latent(x_train) + rnorm(100, sd = 0.1)
x_test <- matrix(runif(3 * 500, -2, 2), ncol = 3)
Estimate the hyperparameters of the additive kernel and, for comparison, of an ARD RBF kernel on all three columns:
additive_model <- optimize_gp(
  x_train,
  y_train,
  kernel = additive,
  noise_variance = 0.05
)
full_model <- optimize_gp(
  x_train,
  y_train,
  kernel = rbf_kernel(length_scale = c(1, 1, 1)),
  noise_variance = 0.05
)

test_rmse <- function(model) {
  sqrt(mean((predict_gp(model, x_test)$mean - latent(x_test))^2))
}

data.frame(
  kernel = c("additive", "ARD RBF on all columns"),
  log_marginal_likelihood = c(
    log_marginal_likelihood(additive_model),
    log_marginal_likelihood(full_model)
  ),
  test_rmse = c(test_rmse(additive_model), test_rmse(full_model))
)
#>                   kernel log_marginal_likelihood  test_rmse
#> 1               additive               49.816680 0.05320361
#> 2 ARD RBF on all columns                9.355743 0.10587888
The additive model has the higher marginal likelihood and about half the error in the latent function at 500 new inputs. The data were generated by an additive function, so here the restriction is correct. When it is not, the marginal likelihood is the place to see it.
Components
Each component f_j is jointly Gaussian with the observations, with \operatorname{cov}(f_j(x_*), f(X)) = k_j(x_*, X), so its posterior mean is
\mathrm{E}[f_j(x_*) \mid y] = k_j(x_*, X)\, \alpha,
where \alpha is stored in the fitted model. The additive kernel’s components are its children:
component_mean <- function(model, index, x) {
  component <- model$kernel$children[[index]]
  drop(evaluate_kernel(component, x, model$x) %*% model$alpha)
}

grid <- seq(-2, 2, length.out = 101)
# Component 1 ignores the second and third columns.
estimate <- component_mean(additive_model, 1, cbind(grid, 0, 0))
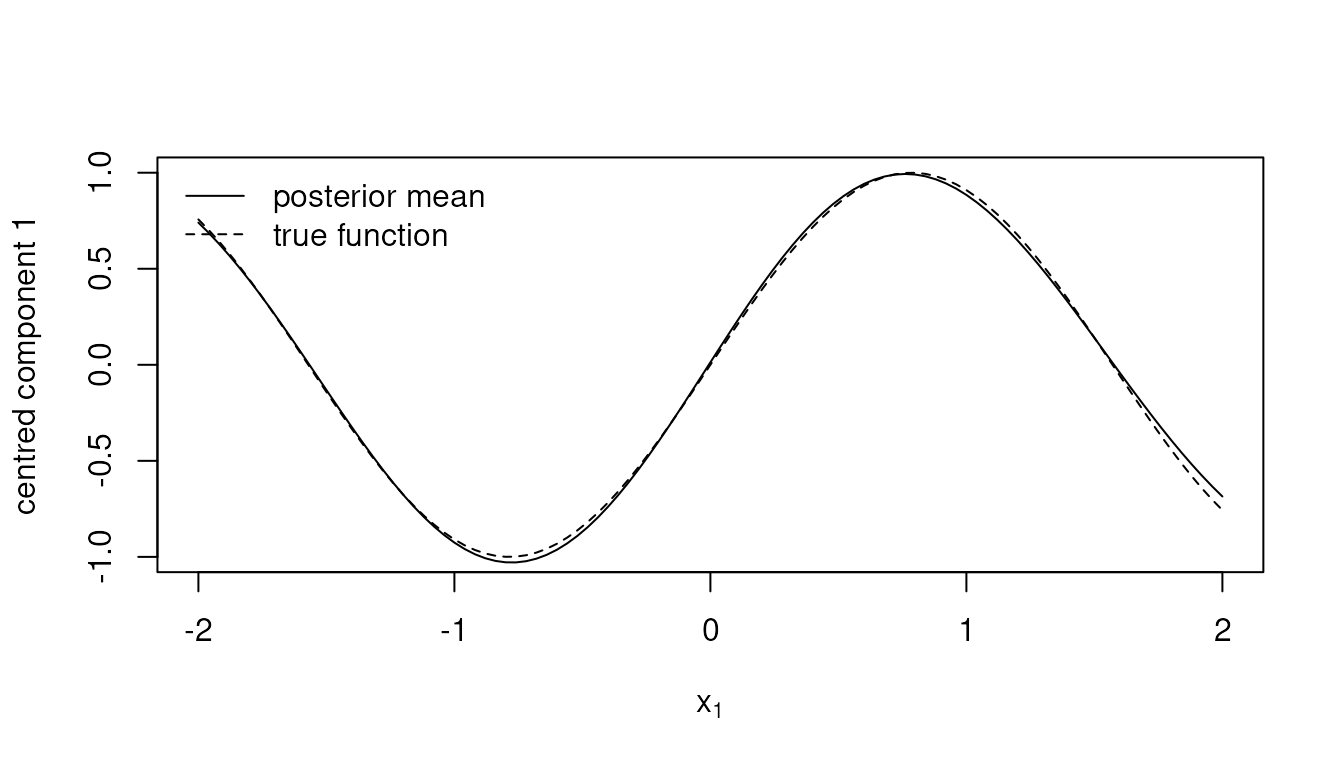
Adding a constant to one component and subtracting it from another leaves f unchanged, so the data identify each component only up to a constant. Centred over the grid, the estimate of f_1 follows \sin(2 x_1):
centre <- function(values) values - mean(values)

plot(
  grid,
  centre(f1(grid)),
  type = "l",
  lty = 2,
  xlab = expression(x[1]),
  ylab = "centred component 1"
)
lines(grid, centre(estimate))
legend(
  "topleft",
  legend = c("posterior mean", "true function"),
  lty = c(1, 2),
  bty = "n"
)